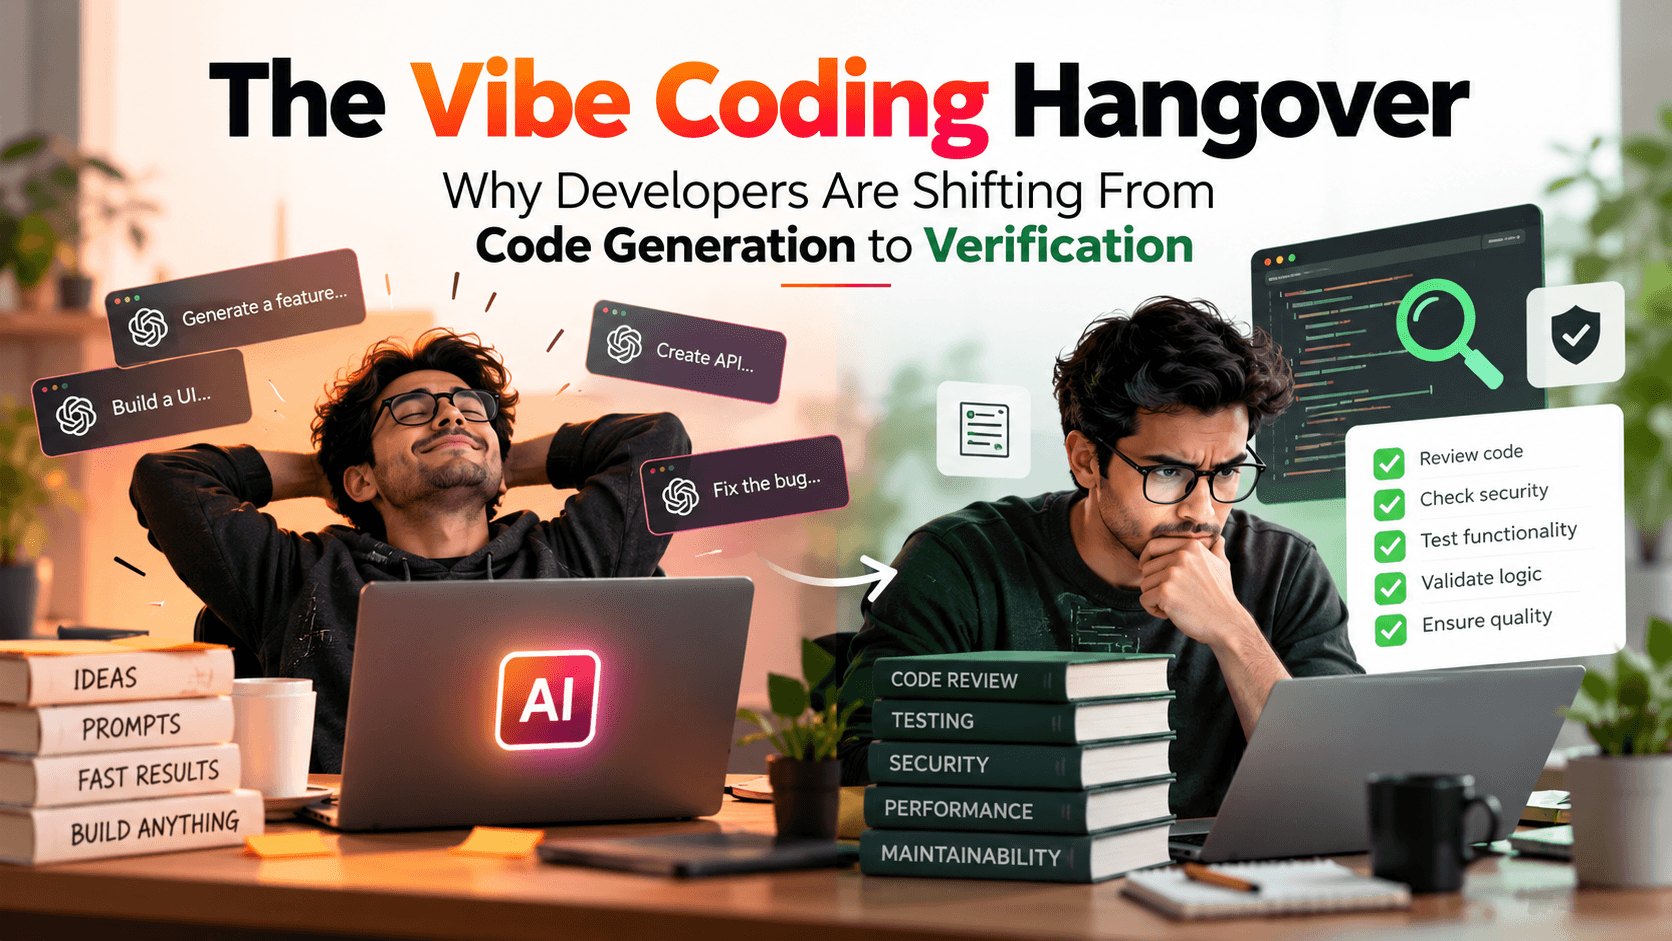
Two years ago, “write me a login page” felt like a magic trick. Today it is a commodity. With Claude Code, Cursor, Codex and a dozen other AI coding agents, any developer can produce hundreds of lines of working-looking code before their coffee cools. Vibe coding (describing what you want in plain language and letting the AI fill in the rest) went from weekend experiment to everyday workflow.
Now the bill is arriving. Teams that pushed agent-generated code straight into production are discovering that typing speed was never the real bottleneck in software engineering. The hard part was always understanding constraints, trade-offs and what the system is actually supposed to do. That is why the frontier of development is quietly shifting from generating code to verifying it.
What Is Vibe Coding, and Why the “Hangover”?
Vibe coding means steering an AI model with natural-language prompts and accepting its output with minimal line-by-line review. For prototypes, internal tools and throwaway scripts, it is genuinely brilliant. You get something running in minutes instead of days.
The hangover starts when that same code meets real users, real data and real edge cases. The code compiles, the demo works, and then an odd bug appears that nobody on the team can explain, because nobody on the team actually wrote or fully read that part of the system. Many developers now describe their job as less “software engineer” and more “full-time reviewer of AI pull requests.”
Problem 1: Silent Assumptions, Not Syntax Errors
Modern models rarely fail on syntax anymore. They fail on assumptions. When an AI agent does not know the exact shape of your API response or how two database tables relate, it usually does not stop and ask. It guesses, commits to the guess, and then builds layers of logic on top of it.
A classic example that frontend developers will recognise instantly:
// AI doesn't know what the API returns, so it covers everything
const isSuperAdmin =
  data.isSuperAdmin === true ||
  data.isSuperAdmin === 1 ||
  data.isSuperAdmin === "true";

// What you actually needed, once the real response was known
const isSuperAdmin = data.isSuperAdmin === true;
This “defensive” code looks harmless, but it is a symptom. The model was uncertain and hid that uncertainty inside the code instead of surfacing it to you. Multiply that across a large feature and you end up with a codebase full of hedges, dead branches and abstractions built for problems that do not exist. That is technical debt accumulating at machine speed.
The fix: give the model ground truth before it writes anything. Paste a real sample API response, a TypeScript interface, a Zod schema or the actual database schema. The less the model has to guess, the less it will invent.
Problem 2: Three Agents Agreeing Is Not Proof
A popular pattern in agentic pipelines looks like this: one agent writes the feature, a second writes the unit tests, and a third reviews the pull request. Everything turns green, and the team ships.
But ask a simple question: were those three checks actually independent? If all three agents received the same incomplete ticket, worked from the same context and were optimised toward the same prompt, their agreement is not validation. It is the same bad assumption echoed three times. Test coverage written by the same intelligence that wrote the bug can easily test the bug as “expected behaviour.”
Real verification needs independence. That means at least one of these:
- Human-owned acceptance criteria written before generation, not derived from the generated code.
- Tests based on real contracts (API specs, schemas, production-like fixtures) rather than on what the implementation happens to do.
- Deterministic tooling such as type checkers, linters, static analysis and dependency scanners that do not share the model’s blind spots.
- A reviewer with domain context who can notice when a premise “smells wrong” before 500 lines are built on it.
Problem 3: One-Shot Features Create Review Debt
It is tempting to ask an agent to build an entire complex feature in one go. The result is often a huge diff that technically works but is exhausting to review properly. When review becomes painful, people skim, and skimming is exactly how silent assumptions slip through.
Developers who get the best results from AI tools tend to work the opposite way: plan first, then implement in small, reviewable increments. Each step is easy to read, easy to test and easy to roll back. Debugging stays manageable because you always know which small change introduced a problem.
The Shift to Verification-Driven Engineering
Safety-critical industries like aviation and space engineering never assumed their engineers were infallible. They built processes around the idea that requirements can be flawed and brilliant people can still be wrong. Software built with AI is now being pushed toward the same maturity. Here is what that looks like in practice.
1. Plan and Interrogate Before You Generate
Use your coding agent’s planning or “ask questions first” modes. Make the AI challenge your requirements and list its assumptions before it writes a single line. Many flaws are cheapest to catch here, at line zero, when fixing them costs one sentence instead of one refactor.
2. Feed the Model Real Contracts
Sample payloads, OpenAPI specs, database schemas and type definitions turn guesses into facts. This single habit removes a large share of hallucinated defensive code.
3. Build Incrementally
Break features into small tasks with clear boundaries. Review, test and commit each one before moving on. Small diffs keep you in control of the codebase you are responsible for.
4. Add Deterministic Guardrails
Strict type checking, linting, sandboxed execution, pinned dependencies and CI checks the agent cannot bypass. These tools do not care how confident the model sounds.
5. Keep Humans on Intent
Let AI handle construction, but keep people responsible for intent: what the system must do, what it must never do, and which trade-offs are acceptable. That is where experience and judgement still matter most.
Quick Checklist: Before You Merge AI-Generated Code
- Can you explain what every changed file does, in your own words?
- Did the model work from a real API response or schema, or did it guess?
- Are there “just in case” branches handling data types that can never occur?
- Were the tests written from requirements, or reverse-engineered from the implementation?
- Did any new dependency get added, and do you actually need it?
- Is the diff small enough that a colleague could review it properly?
Vibe Coding vs Verification-First Development: Side by Side
Vibe coding is not the enemy. It is excellent for prototypes, internal tools and exploring an idea quickly. The problems start when vibe coding output is treated as finished work instead of a first draft. Here is how the two approaches compare in practice:
| Vibe coding | Verification-first development | |
|---|---|---|
| Starting point | A plain-language prompt | A plan, constraints and acceptance criteria |
| Unit of work | Whole features in one shot | Small, reviewable increments |
| Proof it works | “It runs” or another AI agrees | Tests, type checks, linters and human review of intent |
| Main risk | Silent assumptions and review debt | A slower first draft |
| Best for | Prototypes and throwaway scripts | Production code and anything security-sensitive |
For production systems, you do not need to invent a process from scratch. Check AI-generated code against the OWASP Top 10 list of common web application security risks, and borrow from NIST’s Secure Software Development Framework (SSDF), which describes how to build verification into every stage of development. Teams that pair vibe coding with these habits keep the speed without inheriting the hangover.
What This Means for Developers in 2026
None of this means you should stop using AI coding tools. They are here to stay, and developers who use them well are dramatically more productive. (If you are building your AI toolkit, see our list of the best AI productivity tools for remote work in 2026.)
What changes is where your value sits. If your identity as an engineer was mostly about typing syntax, AI has made that skill cheap. If it is about understanding systems, questioning premises, designing architecture and verifying intent, your skills just became more valuable than ever. Industry news is moving in the same direction, with AI labs themselves putting more weight on testing and safety, as covered in our AI news roundup for September 2026.
Generating code is cheap now. Knowing that the code is right is the expensive, human part of the job.
Frequently Asked Questions
What is vibe coding?
Vibe coding is a style of software development where you describe what you want to an AI coding assistant in natural language and accept its generated code with little manual review. It is fast for prototypes but risky for production systems.
Is vibe coding bad?
Not by itself. It is excellent for prototypes, experiments and small internal tools. The problems appear when unreviewed AI code reaches production without clear requirements, real data contracts or independent testing.
How do I reduce AI hallucinations in generated code?
Give the model concrete context before it writes code: sample API responses, type definitions, schemas and explicit acceptance criteria. Ask it to list its assumptions first, and build features in small increments you can review.
Is vibe coding safe for production code?
Vibe coding can be used for production code, but only as a first draft. Before merging, verify it the same way you would a junior developer’s pull request: independent tests, type and lint checks, a security review and a human confirming the code does what the business actually needs.
Will AI replace software engineers?
AI is replacing much of the manual typing, not the engineering judgement. Skills like system design, requirement analysis, code review and verification are becoming more important as code generation becomes cheaper.